The Recall-to-Repair Gap Is Now a Fleet Uptime Crisis
By UpFix
Why fleet uptime is increasingly constrained by software-linked maintenance risk and how to close recall-to-repair delays fast.
The operating models and AI examples in this article are illustrative. They are not a specification of included UpFix features or a measured customer result. See product capabilities and plan limits for the current offer.
Fleet downtime has a new center of gravity: software-linked maintenance risk
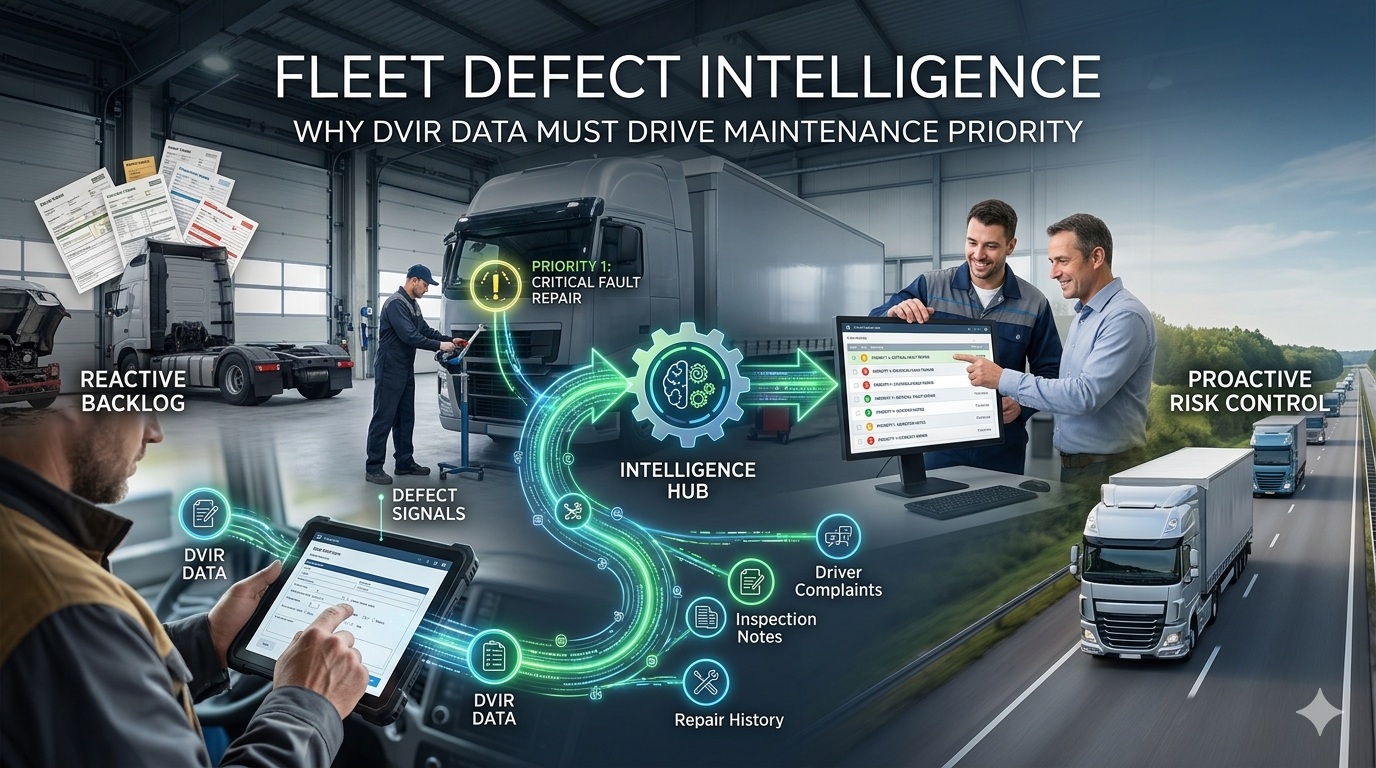
For years, fleet maintenance leaders treated recalls as episodic disruptions and PM compliance as the core uptime lever. That model is now outdated. Recent high-profile recall activity, including software-related braking and lighting concerns in major vehicle populations, highlights a hard shift: reliability risk is moving from isolated components to code-plus-component interactions. The operational consequence is brutal: fleets can be mechanically sound and still operationally fragile.
If your maintenance system cannot triage software advisories, campaign notices, and diagnostic behavior alongside traditional inspections, you are not managing modern fleet risk, you are documenting it after the fact.
Why this matters now
Three trends are converging. First, recall cadence remains elevated across commercial platforms and duty cycles. Second, maintenance labor remains constrained, especially for diagnostics-capable technicians. Third, fleet operators are being measured on service continuity in tighter delivery windows. The old strategy, wait for recall letters, batch repairs later, and absorb interim risk, no longer protects margin or customer trust.
In executive terms: the recall-to-repair gap has become a hidden tax on uptime.
Root cause analysis: where fleets lose reliability leverage
Campaign data is not operationalized
Recall and technical service bulletins are read by compliance teams but often disconnected from route planning, shop loading, and parts positioning decisions.
Diagnostic ambiguity delays action
Software-linked faults can present intermittently. Without historical fault context and failure probability scoring, units are repeatedly “checked and returned,” then fail in service windows.
Maintenance prioritization is calendar-driven, not risk-driven
Many organizations still sequence work by due dates and bay availability instead of mission criticality, safety severity, and consequence of delay.
Knowledge is trapped in technician notes
Valuable troubleshooting logic remains in free text and personal experience. This makes execution variable across sites and shifts.
What good looks like for AI-native fleet maintenance
UpFix is an operations and work management platform with CMMS capabilities. Keep requests, Work Items, procedures, and service history together. Recurring automations require Team or Pro; inventory, analytics, purchasing, and the built-in Assistant require Pro. Connected meter data depends on supported integrations and configuration.
The key shift is philosophical and practical: stop treating recalls as compliance events and treat them as reliability events with measurable uptime impact.
Executive briefing playbook: 8 actions for the next 90 days
- Stand up a recall command cadence: Weekly cross-functional review between maintenance, operations, safety, and procurement.
- Build unit-level risk scores: Combine campaign severity, mileage, duty cycle, and recent fault behavior to rank intervention urgency.
- Redesign shop slotting: Reserve protected capacity for high-risk campaign work to avoid perpetual deferral.
- Pre-position constrained parts: Use expected failure and route criticality to stage inventory before campaign peaks.
- Deploy AI-assisted diagnostics: Surface likely root causes from comparable units and prior fixes before teardown begins.
- Convert technician notes into reusable procedures: Curate top fixes into standardized digital playbooks by platform.
- Tie maintenance plans to dispatch logic: Keep highest-risk units away from mission-critical routes until remediation is complete.
- Track recall-to-repair cycle time as a board metric: Make delay visible, managed, and continuously improved.
Signals to Watch
- Increasing open campaign count per 100 vehicles
- Rising “repeat fault within 14 days” rates after repair
- Growing parts backorder impact on campaign closures
- Mismatch between dispatch-critical assets and unresolved safety actions
- Escalation in roadside events tied to known advisories
Contrarian insight: compliance is not reliability
Many fleets report strong compliance while still missing service-level targets. That is not a contradiction; it is a systems design problem. Compliance tells you the process existed. Reliability tells you the risk was actually reduced. AI-native maintenance closes that gap by making every diagnostic event, campaign action, and work-order closure part of a continuous learning system.
The operators who win the next cycle will not be those with the most dashboards. They will be the ones who collapse time between signal, decision, and repair, and prove it in uptime outcomes.